The Large Model Systems Organization develops large models and systems that are open, accessible, and scalable.
Latest Blog
See all posts
Humming in SGLang: Flexible Low-Bit Kernels for Efficient MoE Serving
Humming is a lightweight, JIT-compiled kernel library for quantized dense and mixture-of-experts (MoE) inference. Its SGLang integration connects low-bit checkpoints to specialized kernels while preserving the framework’s routing, scheduling, and distributed execution.
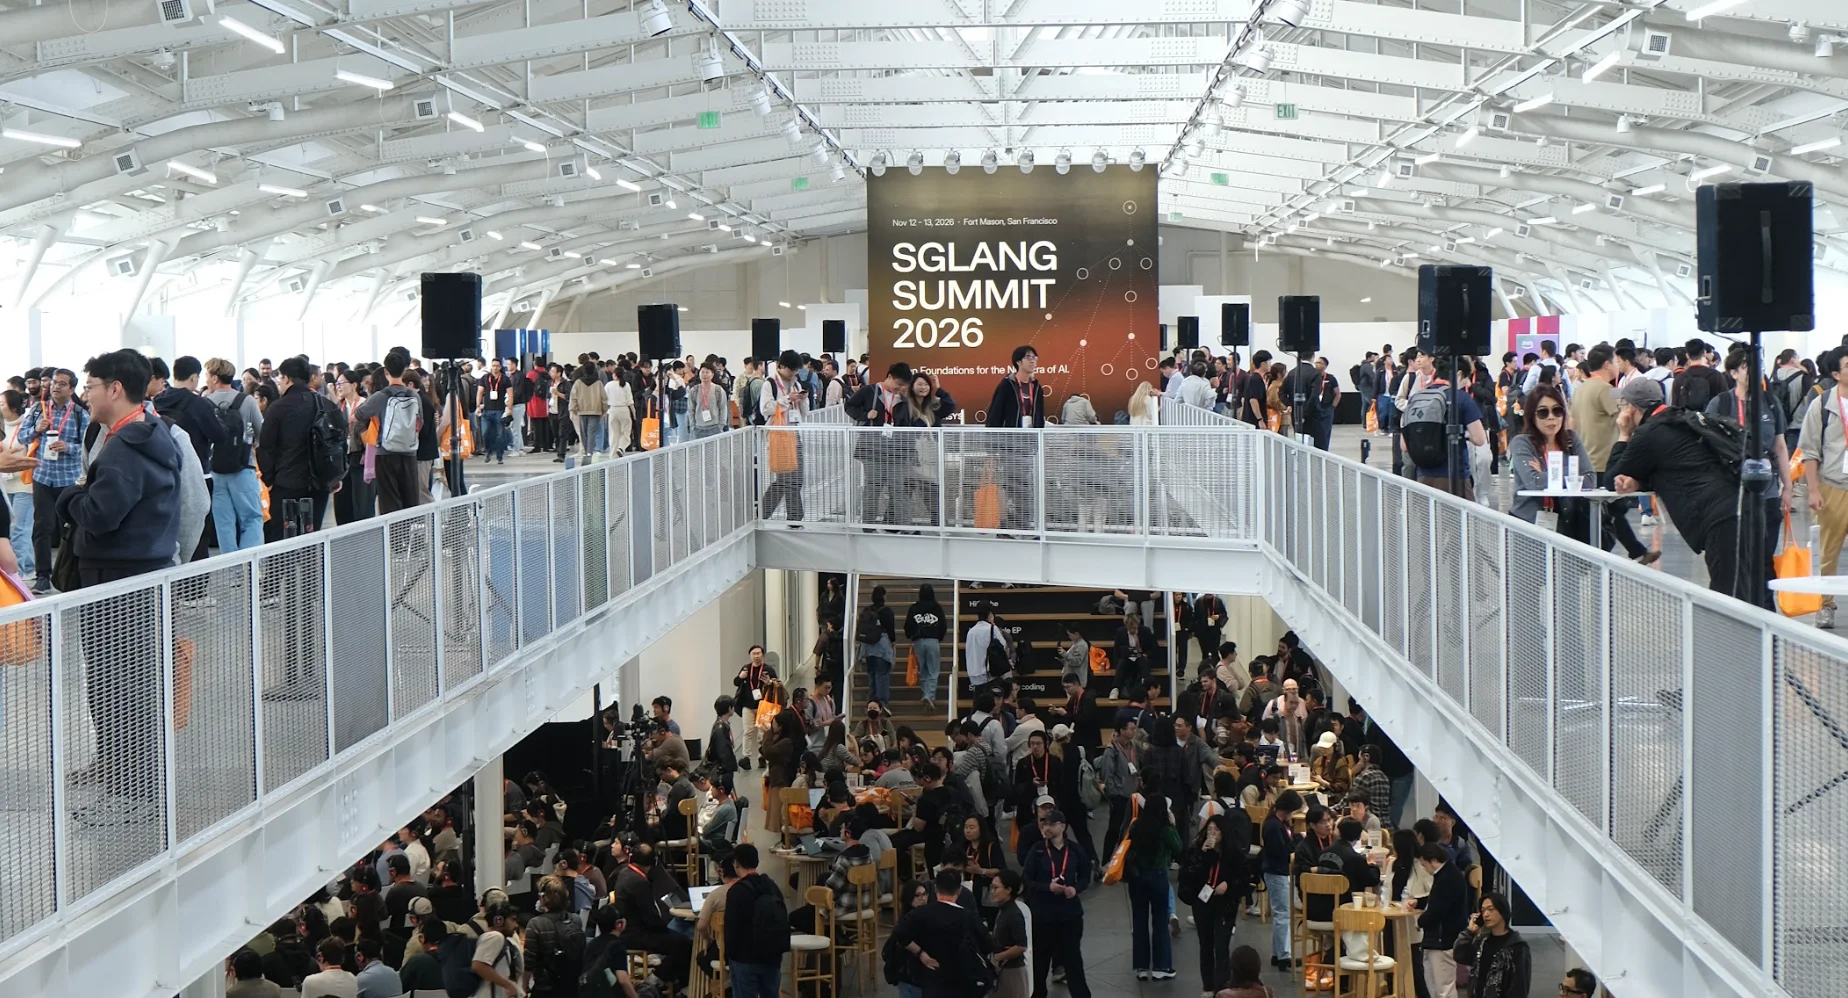
SGLang Summit 2026 Recap: Building Open AI Infrastructure Together
More than 2,000 developers, researchers, and industry leaders gathered at Fort Mason in San Francisco on November 12–13 for the first SGLang Summit.
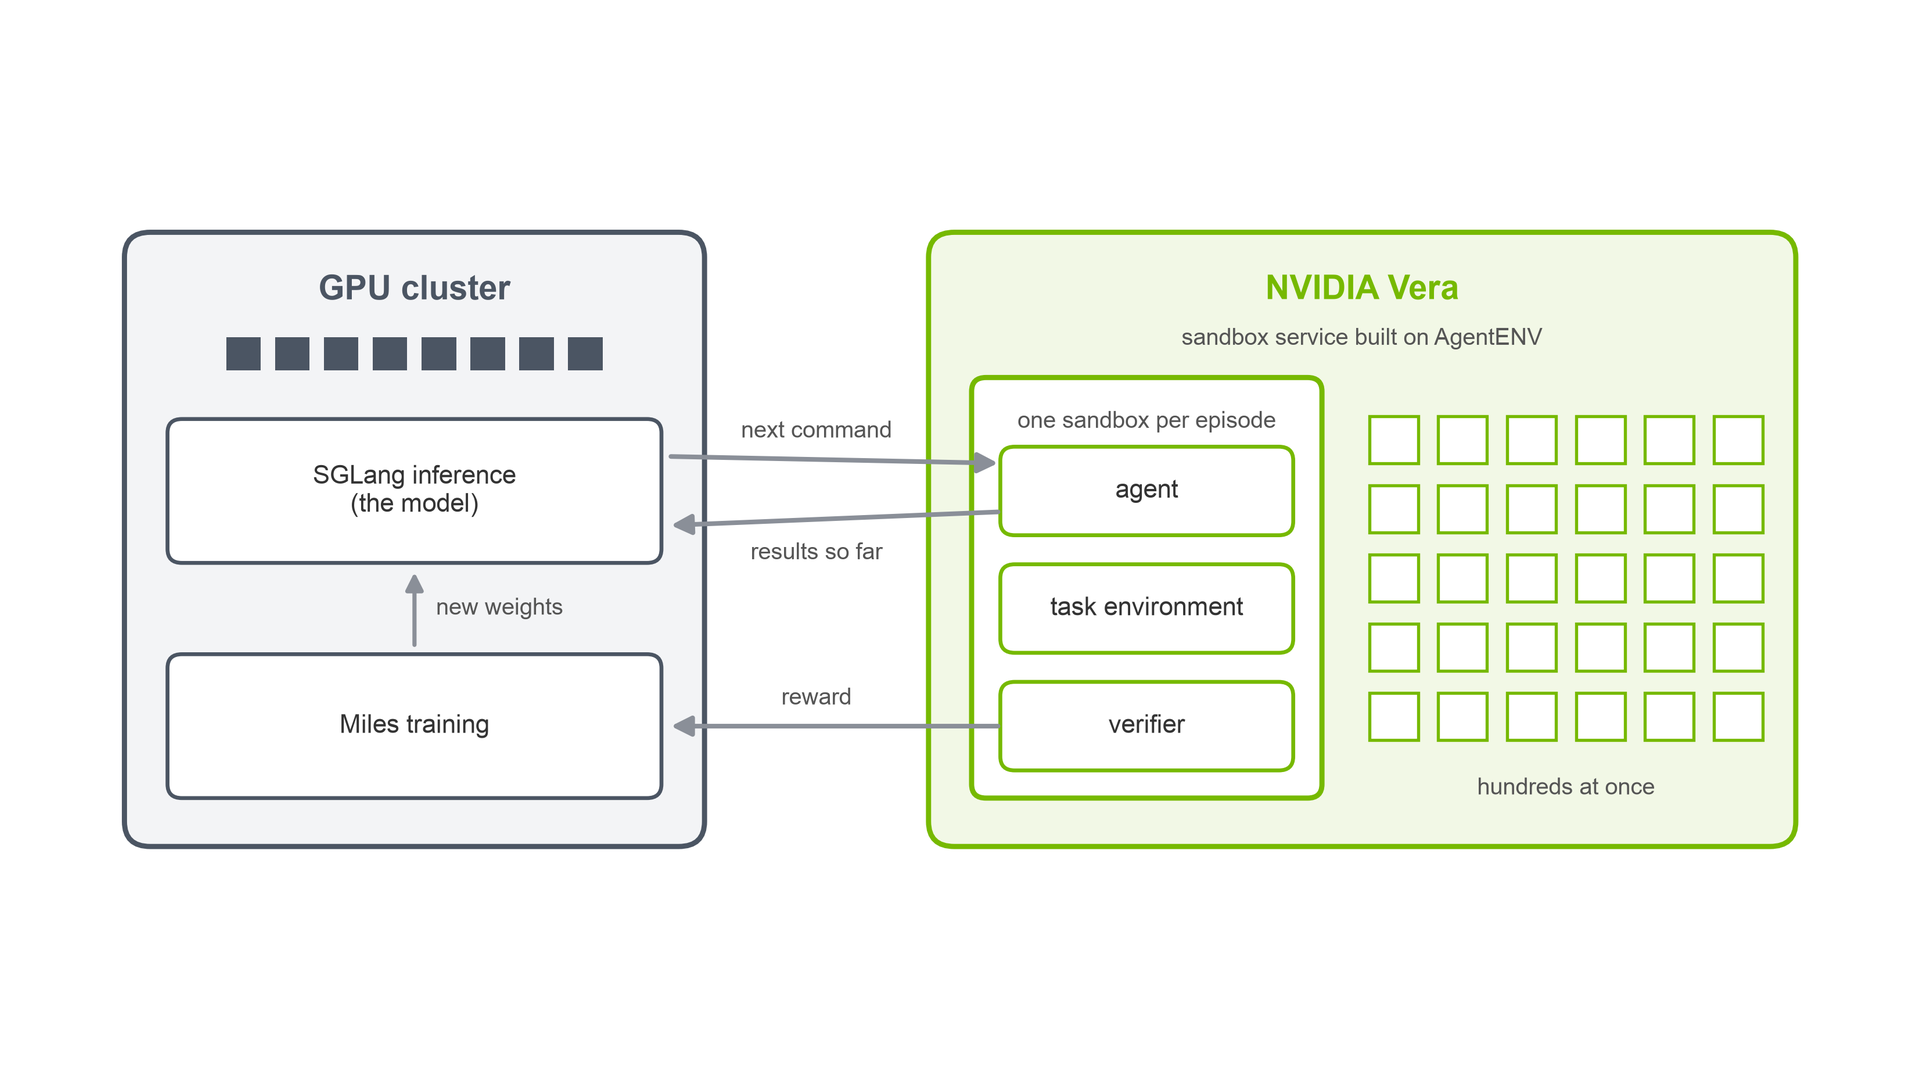
RadixArk Miles runs agentic RL training on NVIDIA Vera CPUs: faster sandboxes, faster training
In agentic RL, the model does more than write text: it runs commands in a sandbox, compiles code and runs tests, and decides its next step from the results. A training run can keep hundreds of sandboxes or more open at once, and the CPUs that run them can affect the speed and scale of training.
Projects
View all projects



Our Sponsors & Partners
Backed by leading companies and institutions advancing AI research.
Voltage Park, NVIDIA, Nebius, Google Cloud, AtlasCloud, a16z, AMD, InnoMatrix, Laude Institute, Hyperbolic, NovitaAI, Verda Cloud, Sky9, Kaggle, MBZUAI, Together, RunPod, Anyscale, HuggingFace