SGLang Adds Day-0 Support for NVIDIA Nemotron 3.5 Super VL
Always-on AI agents must do more than generate text. They need to interpret visual information, reason across long-running tasks, and use tools reliably across documents, applications, and video.
NVIDIA Nemotron 3.5 Super VL is an open multimodal model designed for text, image, document, and video inputs, with text output for agentic reasoning and tool use. Its mixture-of-experts architecture has 120 billion total parameters and activates 12 billion parameters per token.
Nemotron 3.5 Super VL is built for customization and deployment in specialized enterprise workflows. Within the Nemotron 3 family of models, it serves as the high-accuracy multimodal execution model, complementing Nemotron 3.5 Lightning and Nemotron 3 Ultra.
For production serving, SGLang provides a high-performance path for continuous batching, prefix reuse, speculative decoding, and OpenAI-compatible APIs.
This blog covers the quick start guide to deploy the model with SGLang.
TL;DR
- Architecture: 120B-parameter mixture-of-experts model with 12B active parameters per token.
- Modalities: Text, images, documents, and video in; text out.
- Core optimizations: C-RADIOv4 vision encoding, a hybrid Mamba-Transformer architecture, multi-token prediction (MTP), and NVFP4 quantization.
- Agentic role: High-accuracy, multimodal understanding and execution for agents that see, reason, and act.
- Customization: Post-trained with NVIDIA NeMo for domain adaptation and specialized workflows.
- Serving: SGLang-based deployment with OpenAI-compatible APIs, prefix caching, continuous batching, and speculative decoding.
- Deployment targets: DGX Spark, 1x GB10, B200, B300, RTX PRO 6000, H200, and 2x H100
- Edge Device Performance: Runs locally on a single DGX Spark and RTX 6000 PRO, achieving 243.9 tok/s on the latter
- Download the model weights from Hugging Face: BF16 and NVFP4
- Run Nemotron 3.5 Super VL with SGLang using the getting-started cookbook.
Installation and Quick Start with SGLang
SGLang provides a serving layer for high-throughput multimodal inference with continuous batching, prefix caching, speculative decoding, and an OpenAI-compatible API.
docker pull lmsysorg/sglang:v0.5.21

docker run --rm -it \
  --gpus all \
  --network host --ipc host \
  -v ~/.cache/huggingface:/root/.cache/huggingface \
  --entrypoint /bin/bash \
  lmsysorg/sglang:v0.5.21
Start the model server inside the container:
sglang serve \
  --model-path nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 \
  --trust-remote-code \
  --reasoning-parser nemotron_3 \
  --speculative-algorithm EAGLE \
  --speculative-num-steps 5 \
  --speculative-eagle-topk 1 \
  --speculative-num-draft-tokens 6 \
  --port 8000
Optimized Inference with Multi-Token Prediction
Nemotron 3.5 Super VL includes built-in multi-token prediction heads. MTP can accelerate long-running agentic workloads by proposing multiple future tokens and verifying them during decoding, while preserving the model’s output quality target.
SGLang can expose speculative decoding controls at launch time. With MTP, SGLang can achieve 243.9 tok/s on a single RTX 6000 PRO.
Run Nemotron 3.5 Super VL with MTP
sglang serve \
  --model-path nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 \
  --trust-remote-code \
  --speculative-algorithm EAGLE \
  --speculative-num-steps 5 \
  --speculative-eagle-topk 1
Built for Specialized, Always-On Agent Workflows
Nemotron 3.5 Super VL combines agentic execution with visual understanding. It can reason over screenshots, documents, application interfaces, and video while producing text that an agent can use to plan actions, call tools, and continue a workflow.
Organizations can use NVIDIA NeMo to adapt the model for domain-specific terminology, tasks, policies, and tool-use patterns. The goal is a controllable model that can be specialized without giving up a consistent deployment path.
Example Use Cases
- Customer service: Interpret screenshots, forms, receipts, and account documents while guiding or executing the next action.
- Document intelligence: Extract, compare, and reason across visually rich reports, presentations, tables, and scanned material.
- Enterprise productivity: Understand application interfaces and support multi-step workflows across business software.
- Video understanding: Analyze long-form video and connect visual events to an agent’s reasoning process.
- Web research: Combine page understanding, visual interpretation, and tool use across iterative research tasks.
Accuracy and Efficiency for Multimodal Agent Tasks
The model’s sparse 120B-parameter architecture activates 12B parameters per token to balance model capacity with serving efficiency. The hybrid Mamba-Transformer design, MTP, LatentMoE, and NVFP4 quantization are intended to improve throughput and memory efficiency for long-context, multimodal agent workloads.
As shown in Figure 1, on a single GPU, this model delivers up to 5x faster throughput for agentic tasks compared to other open models in its size category.
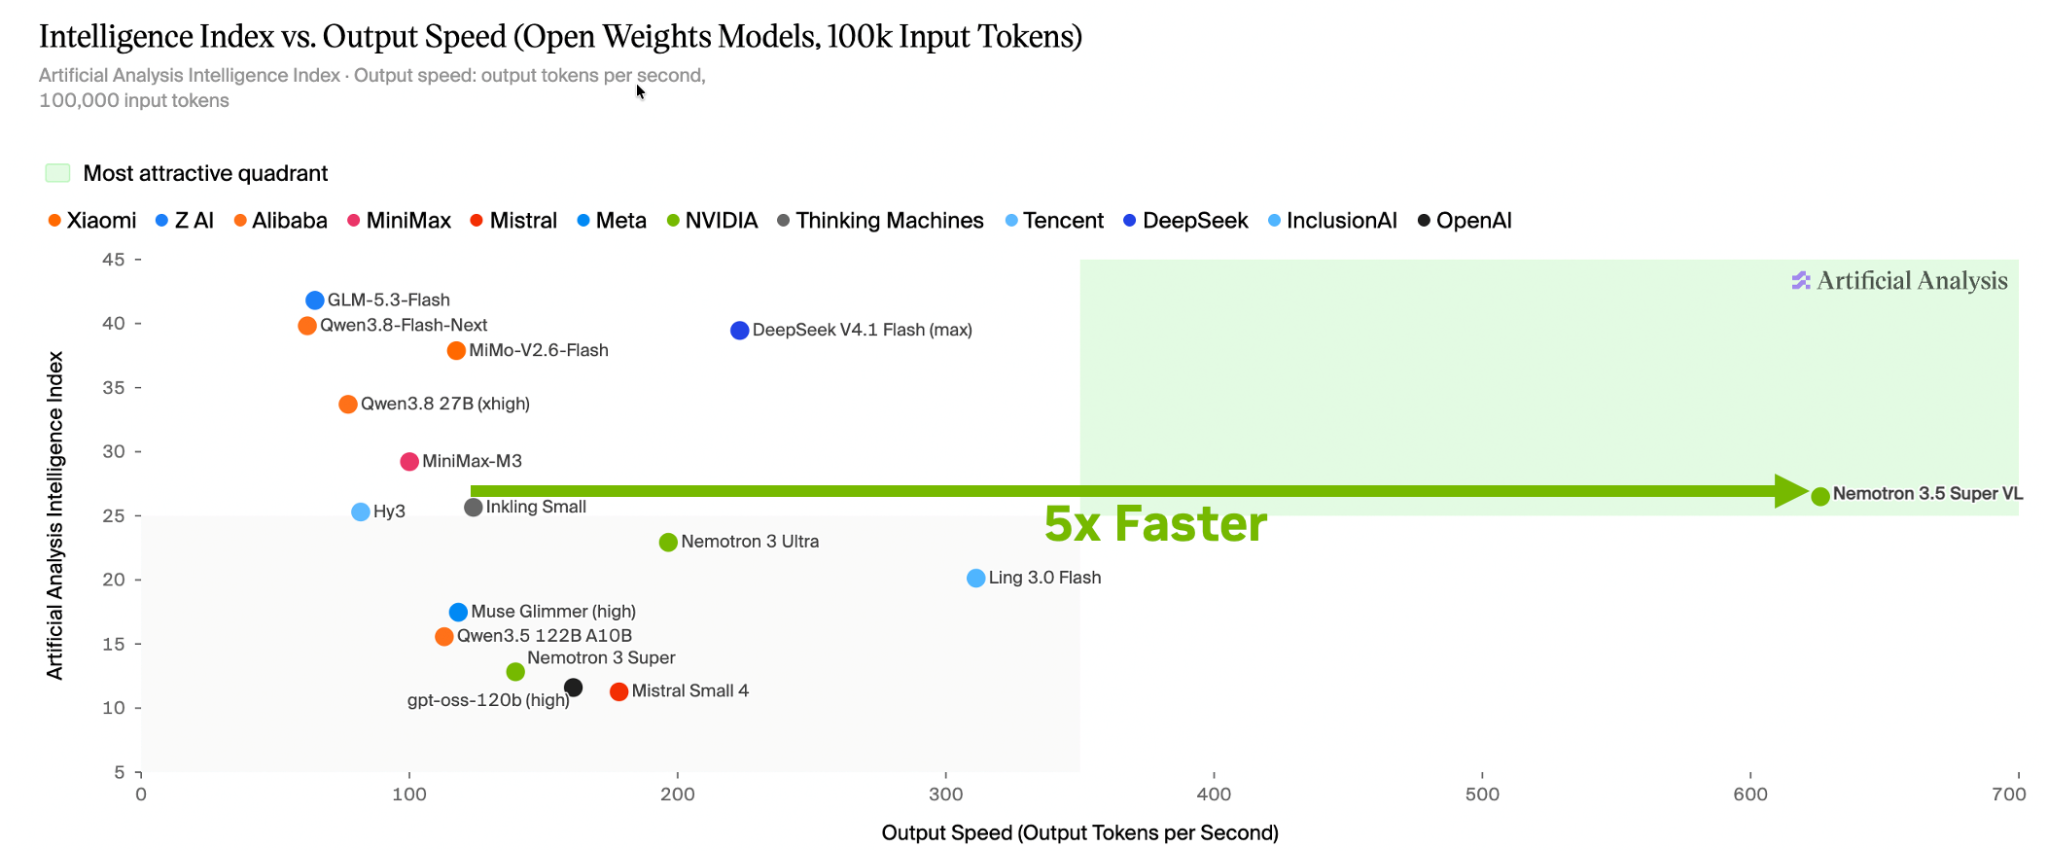
Figure 1. Nemotron 3.5 Super VL delivers over 600 TPS on Artificial Analysis Intelligence Index agentic tasks on Baseten endpoint.
As shown in Figure 2, Nemotron 3.5 Super VL performs tasks 4x faster compared to other leading open models of similar size.
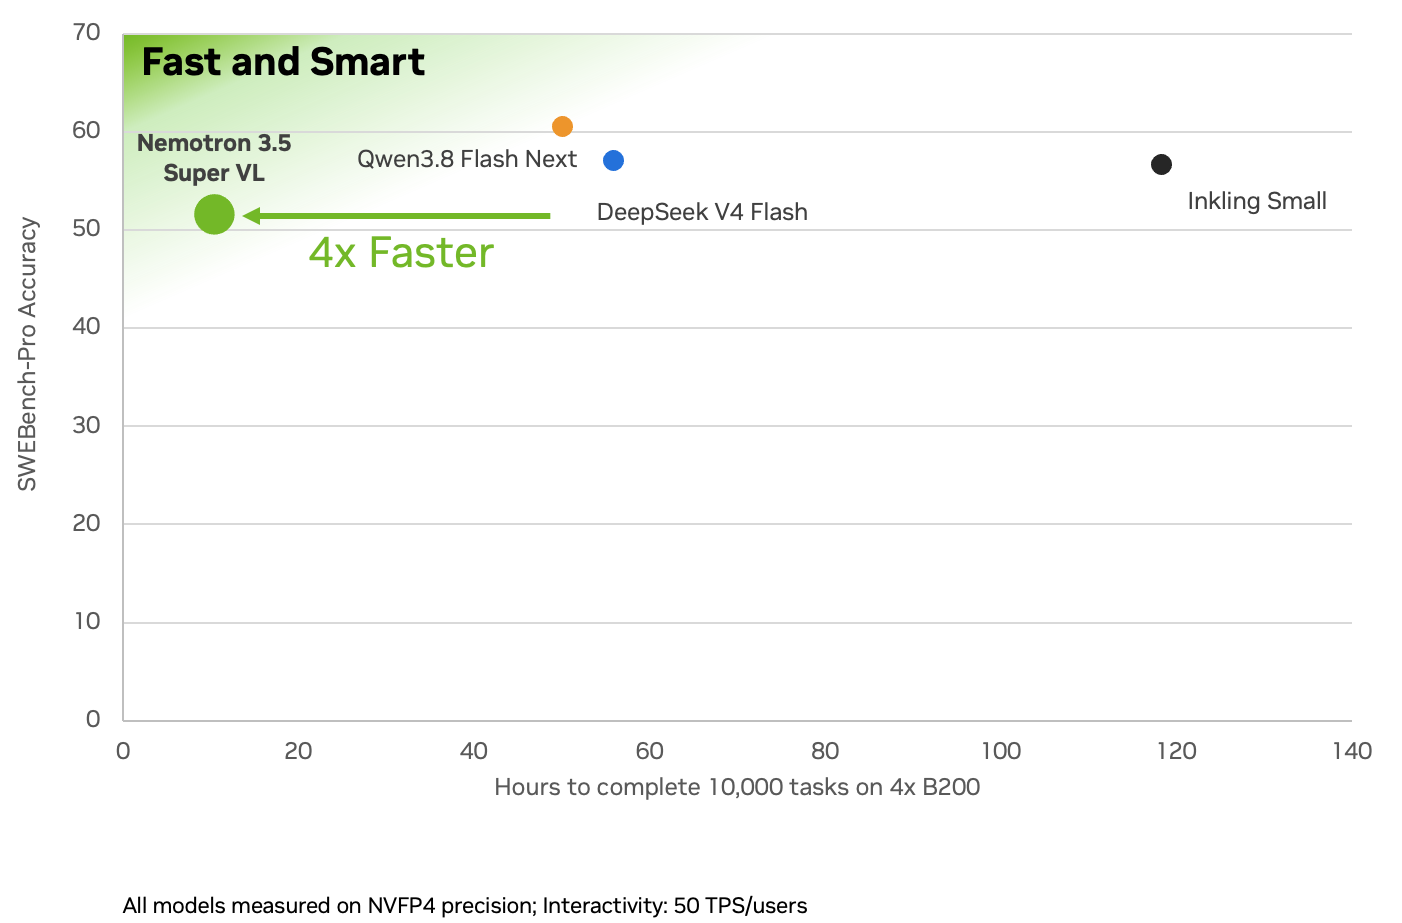
Figure 2. Nemotron 3.5 Super VL takes advantage of higher throughput and token efficiency to deliver 4x faster task completion.
Get Started
- Download the model weights from Hugging Face: BF16 and NVFP4
- Run Nemotron 3.5 Super VL with SGLang using the getting-started cookbook.
Acknowledgements
Nirmal Kumar Juluru, Anusha Pant, and Faradawn Yang.